Ruthless Evaluator vs AI Agentic Workflows: The Difference Behind the Interface
A custom AI workflow can generate useful proposal feedback. Ruthless Evaluator adds the security, maintained EU evaluation logic, institutional consistency, repository and portfolio intelligence needed for repeatable quality assurance.
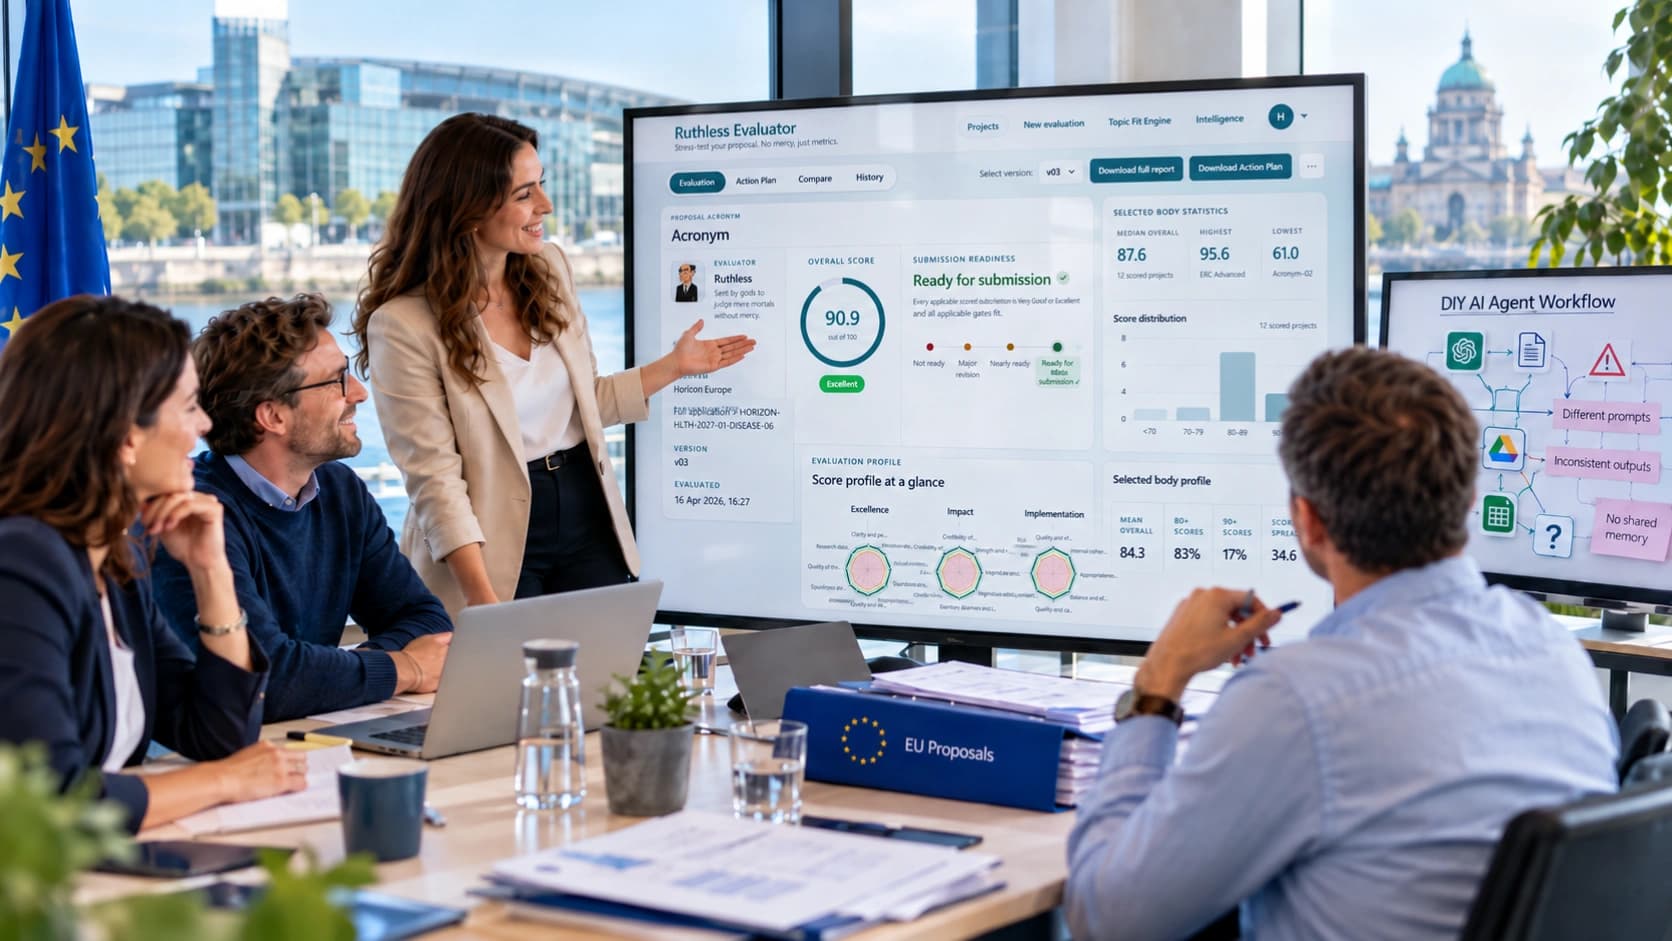
A question we increasingly hear from technically capable research organisations is perfectly reasonable: if we can build an AI agent workflow that reads a proposal and returns comments, why should we use Ruthless Evaluator?
The short answer is that a strong custom workflow can reproduce parts of the visible experience. It can read proposal text, consult reference material, distribute tasks across specialist agents, return criterion-level comments and suggest improvements. For an expert individual or a narrow internal experiment, that may be enough.
The important comparison begins after that first demonstration. A workflow that can analyse one proposal is not automatically an institutional proposal quality-assurance system. The difference appears in everything that must surround the model: confidentiality, data retention, access controls, maintained EU evaluation logic, consistency across users, evaluation history, analytics, testing and continuous maintenance.
A convincing prototype can still be only the first layer
Modern AI tooling makes it surprisingly fast to assemble a proposal-review workflow. A team can combine a frontier model with instructions, retrieval, official documents, structured outputs and several specialist steps. The resulting report may look very similar to the output of a dedicated product.
Comparing screenshots or a single output is therefore not enough.
The stronger question is whether the organisation can rely on the complete system every time a different researcher, team or department uses it, across different EU programmes and over several years. That requires a system that remains secure, consistent, current, traceable and useful after the first evaluation has finished.
We made a similar distinction in Ruthless Evaluator vs ChatGPT. General AI capability matters, but EU proposal evaluation depends on the framework, controls and evidence surrounding the model.
1. Confidentiality and security are part of the product, not an afterthought
EU funding proposals can contain unpublished science, patentable technical details, commercial strategy, partner information, customer evidence, financial projections, regulatory plans and weaknesses that an applicant has not disclosed publicly. For universities, research centres and companies, the security question is therefore not optional.
A useful comparison starts with the complete data path. Which systems receive proposal content? Where is the original file stored? Is the content copied into a vector database, file store, tracing system or third-party tool? What happens on cancellation or failure? Who can access the results? What is logged? What does the model provider retain?
A custom workflow can answer all of these questions well, but somebody has to design, verify and maintain every answer.
Ruthless Evaluator treats this as a core product responsibility. The current architecture separates the temporary proposal input from the structured evaluation record that the user needs to keep. The uploaded PDF or DOCX is processed inside the Ruthless Evaluator environment, the required text is extracted for evaluation, and the original uploaded proposal file is automatically deleted after successful processing, cancellation or failure. Full proposal files are not stored in the application database. Abandoned temporary inputs are also covered by bounded cleanup safeguards.
The model layer receives the proposal text required for the requested analysis. Ruthless Evaluator does not send the original proposal through OpenAI Files, File Search or Vector Stores as part of the evaluation path. Structured evaluation outputs remain available through authenticated access so that users can revisit evaluations, compare versions and use the wider product functionality.
That design is described publicly on the Ruthless Evaluator Security and Confidentiality page.
2. Ruthless Evaluator has Zero Data Retention enabled under a written OpenAI agreement
There are two privacy questions that are often mixed together.
First: is customer content used to train the underlying model? OpenAI states that API data is not used to train or improve OpenAI models by default unless the customer explicitly opts in.
Second: can customer content be retained by the API provider after the request? Under standard API controls, OpenAI documentation states that abuse-monitoring logs may contain customer content and may normally be retained for up to 30 days. OpenAI also provides Zero Data Retention, or ZDR, for eligible customers, subject to approval, configuration and endpoint limitations. The current OpenAI data controls documentation explains these differences.
Koncentriq and OpenAI have signed a written agreement enabling Zero Data Retention for the OpenAI API project used by Ruthless Evaluator, and ZDR is active in the Ruthless Evaluator production configuration. This is not a general assumption based on using an API. It is an approved data-retention arrangement that has been enabled for the covered production processing.
For the relevant ZDR-enabled API requests, OpenAI documentation states that customer content is excluded from abuse-monitoring logs and that the store parameter for eligible Chat Completions and Responses processing is treated as false. Ruthless Evaluator also configures covered model requests without provider-side application storage.
There is an important nuance for teams building their own agent systems. ZDR and agentic architecture are not mutually exclusive, but ZDR is not automatically inherited because a workflow uses agents. OpenAI currently marks the managed /v1/agents endpoint as not eligible for ZDR, while endpoints such as Chat Completions and Responses can be eligible subject to the documented limitations. A custom agentic workflow can therefore be designed around ZDR-compatible primitives, but the institution must obtain the required approval and verify every endpoint, tool and external service in the data path.
This is why the correct security comparison is not "AI agent versus ZDR". It is a self-managed data architecture versus a production architecture where the retention controls, eligible processing path and provider agreement have already been established and maintained.
We explain the agreement and its implications in more detail in Koncentriq and OpenAI enable Zero Data Retention for Ruthless Evaluator.
3. Security extends well beyond ZDR
ZDR is important, but it is only one layer. A secure institutional workflow also needs strong access controls, disciplined software delivery and monitoring.
Ruthless Evaluator uses authenticated access, server-side session validation, secure cookie controls, refresh-token rotation and revocation mechanisms, and multi-factor authentication for privileged administrative functions. Evaluation outputs are logically separated by user and project. Administrative access is restricted, role based and logged for legitimate operational purposes.
The development and deployment process also includes automated checks for secrets, application security issues, vulnerable dependencies and container vulnerabilities, together with controlled staging validation before production. Security monitoring is designed around minimised operational metadata rather than proposal content, with alerts for defined abnormal activity and documented incident-response procedures.
Core application and managed database systems are hosted in Frankfurt, Germany, and institutional customers can use documented data-processing terms and supporting security documentation for procurement or data-protection review.
A capable institution can build equivalent protections internally. The point is not that these controls are impossible to reproduce. The point is that they are part of the system that has to be built, tested, operated and reviewed continuously. A diagram with several AI agents does not provide them by itself.
4. EU evaluation logic requires continuous programme maintenance
A proposal-review workflow is only as good as the evaluation framework it applies.
A team can load a Work Programme, an application template and an evaluation form into an AI workflow. That can work well. The maintenance problem begins when those sources change, when a new programme year starts, when a template is revised, when criteria differ by stage or when two instruments that look similar require different evaluation logic.
Ruthless Evaluator maintains programme-specific evaluation configurations built around applicable Work Programmes, official templates, evaluation forms, criteria, subcriteria and programme guidance. The user does not need to rebuild that source set and evaluation logic for every analysis.
This matters because a fluent AI response can still be the wrong evaluation if it uses an outdated template, the wrong stage, incomplete criteria or a framework that does not match the call. In an internal system, somebody must own source monitoring, version control, methodology updates, regression testing and release decisions.
5. Institutional consistency cannot depend on every user building a separate workflow
A personal AI workflow naturally reflects the person who built it. Different users choose different prompts, source files, model settings, scoring approaches, agent roles and revision strategies. Even when a team starts from the same template, local changes accumulate.
For institutional use, that variation becomes a governance problem when results need to mean the same thing across people and teams.
Ruthless Evaluator provides a central evaluation layer. Users working with the same supported programme use the same maintained evaluation framework and structured methodology. That makes results easier to compare, quality practices easier to standardise and institutional use easier to govern.
A research centre can absolutely create the same consistency with an internal platform. It then needs central ownership of prompts, rubrics, source sets, model versions, scoring logic, output schemas, release testing and change control. At that point, the organisation is already operating a software product rather than a collection of personal agent workflows.
Consistency matters at proposal level too. Our guide to Horizon Europe proposal consistency shows how easily strong individual sections can still fail to reconcile across objectives, evidence, resources, risk and impact. The evaluation method itself deserves the same discipline.
6. The evaluation repository creates institutional memory
A one-off workflow often ends when the answer appears on screen. Ruthless Evaluator is designed so that the evaluation becomes part of a structured history.
Users can return to previous evaluations, inspect project versions, compare how a proposal evolved and retain the structured outputs required for future review. The original uploaded proposal remains transient, while the evaluation evidence needed for the product remains available in the authenticated workspace until customer deletion.
For an individual, this avoids losing valuable feedback across files and chats. For an institution, it creates something more important: a common evaluation repository from which quality can be reviewed over time.
Building that capability internally adds database, tenant isolation, permissions, deletion, export and version-history responsibilities that sit outside the agent itself.
7. Ruthless Intelligence changes the unit of value from one proposal to the whole portfolio
This is where the comparison changes most substantially.
A conventional AI workflow answers a document-level question: what is strong or weak in this proposal?
Ruthless Intelligence answers a second-order question: what does the history of our evaluations reveal about how we build proposals?
Ruthless Intelligence analyses the structured evaluation history already created in Ruthless Evaluator. At portfolio level it can examine project counts, evaluation coverage, represented programmes, Submission Readiness distribution, score statistics, repeated strengths, recurring growth areas, emerging signals, quality evolution and projects that deserve attention.
The important word is repeated. A single strong or weak proposal should not define an organisation. Ruthless Intelligence looks for patterns across comparable projects and distinguishes stronger evidence from isolated observations. It also keeps incompatible programme or stage frameworks separate rather than averaging numbers that should not be compared.
That turns evaluation from a one-time quality check into an organisational learning loop.
8. You can analyse any relevant subset, not only the entire organisation
Institutional analytics are useful only if the organisation can ask focused questions.
Ruthless Intelligence allows a user to build an analysis around a selected body of work. That can represent one researcher, a team, a unit, a programme cohort or a custom selection of projects. The analysis can work from the latest version of each project, compare first and latest versions, or examine the wider evaluation history depending on the question being asked.
This means a research office can investigate questions such as:
- Does one researcher repeatedly under-support impact claims?
- Is a department improving commercial logic across successive applications?
- Do proposals in one programme show the same implementation weakness?
- Which strengths recur across a selected team and should be preserved?
- Are revisions actually improving the quality signals that matter?
The quantitative layer behind Ruthless Intelligence is deterministic. It owns counts, medians, score distributions, readiness states, compatibility groups, pattern classifications and project evolution. AI interpretation works from a bounded analytical digest and evaluator-derived evidence rather than inventing the underlying statistics.
Completed analyses are saved as snapshots, so the organisation can return to what the evidence showed at a particular point in time. This creates a quality-assurance memory that a collection of disconnected chats or one-off agent runs does not naturally provide.
9. The hidden cost of a DIY workflow appears in maintenance
The first version of an AI workflow can be fast to build. The long-term workload appears after it starts being relied upon.
Programme documents, templates, evaluation forms, models, APIs and security requirements all change. A model or prompt update can improve one area while altering scoring or degrading another, and a new tool can introduce a new retention path.
A maintained institutional system therefore needs continuous work across four areas:
- Programme maintenance: Work Programmes, templates, criteria, guidance and evaluation logic.
- Technical maintenance: models, APIs, schemas, error handling, compatibility and observability.
- Security maintenance: data flows, provider controls, access rules, retention, monitoring and incident response.
- Quality maintenance: regression testing, scoring behaviour, evidence standards and output consistency.
Ruthless Evaluator absorbs that maintenance as part of the product. An internal workflow transfers the same responsibility to the institution. The relevant comparison is therefore not subscription price versus API tokens. It is managed product versus internal product ownership.
10. When building internally can still make sense
A custom workflow can be the right choice when an organisation has strong engineering and security ownership, a narrow use case, unusual integrations or a strategic reason to own the full platform. Agent workflows are also excellent for experimentation and specialised internal automation.
The mistake is not building an agent. The mistake is assuming that a successful prototype and an institutional quality-assurance system are equivalent because both can generate useful proposal comments.
If the institution is willing to own security, programme updates, evaluation methodology, storage, analytics, testing and long-term maintenance, building internally can be a legitimate decision. Otherwise, the apparent saving can become hidden operational work.
11. Eight questions that reveal the real comparison
Before treating a custom AI workflow as an institutional substitute, ask eight questions:
- What exact systems receive proposal content? Include the model provider, tools, file services, vector stores, tracing systems and external integrations.
- What is retained, where and for how long? Distinguish no-training commitments from retention controls and verify whether ZDR is actually approved and enabled for the chosen path.
- What happens to the original uploaded document? Define processing, deletion, cancellation, failure and abrupt-interruption behaviour.
- Who maintains the official EU source framework? Someone must own Work Programmes, templates, evaluation forms, criteria, programme years and release validation.
- How is evaluation behaviour standardised across users? Control methodology, prompts, rubrics, model versions, sources and output schemas if results need to be comparable.
- Where does evaluation history live? Define versioning, access control, deletion, export and institutional continuity.
- Can the organisation learn across proposals? Determine whether repeated strengths, recurring weaknesses, readiness patterns and quality evolution can be analysed for the full portfolio or selected groups.
- Who owns the system next year? Name the people responsible for programme maintenance, security, technical changes and quality regression testing.
If those questions already have strong answers, the organisation may be building a serious internal platform. If they do not, the workflow may still be a valuable personal tool, but it should not be confused with institutional-grade proposal quality assurance.
The difference is not the model. It is the system around it.
AI agents are powerful, and a sophisticated custom workflow can generate excellent proposal feedback. The difference is what surrounds that output.
Ruthless Evaluator combines confidential proposal handling, a written OpenAI ZDR agreement active in production, controlled access, maintained EU evaluation logic, standardised methodology, a structured evaluation repository, continuous maintenance and Ruthless Intelligence. The result is designed to work not only for one expert evaluating one proposal, but for repeated professional and institutional use.
And Ruthless Intelligence adds the part that a one-off workflow usually misses completely: the ability to transform many individual evaluations into evidence about the organisation itself, globally or for any selected group of projects.
A custom agent can reproduce many of these components. If an organisation reproduces all of them, it has moved well beyond a simple AI workflow.
It has chosen to build, secure, validate and maintain its own proposal quality-assurance platform.
Run an evaluator grade review on the draft
Upload a version, select programme context, and get structured feedback you can act on.